When monitoring stops scaling
What a simulation suggests about the cost of overseeing a growing agent portfolio.
Read moreIdeas across time · Research
Simulations I run when I want to know if an idea about AI survives contact with real numbers.
Pre-registered campaigns
Each campaign writes down its predictions before a single unit runs, then reports what held, what failed and what the result does not claim. 10 campaigns so far.
Paper ·
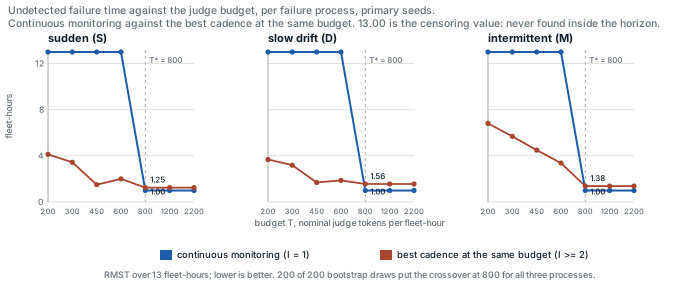
A pre-registered simulation held hourly monitoring of an agent fleet and six-hourly inspection to the same nominal reviewer budget, and found the budget at which hourly monitoring starts to catch faults.
Read the paperAnnual report · 2026
The lab’s annual report: the Delegation Index, the protocol, seven pre-registered campaigns, the corrections logged and every measured claim, in one document.
Read the reportThree-part publication · September 2026
A self-hosted service that answers a workflow's typed questions with a calibrated probability. The executive briefing, the full paper and the blog post that started it.
Open the publicationFilm · October 2026
The lab’s work on AI delegation and oversight in one film of just under nine minutes, with chapters, a full transcript and every number on screen listed with its source.
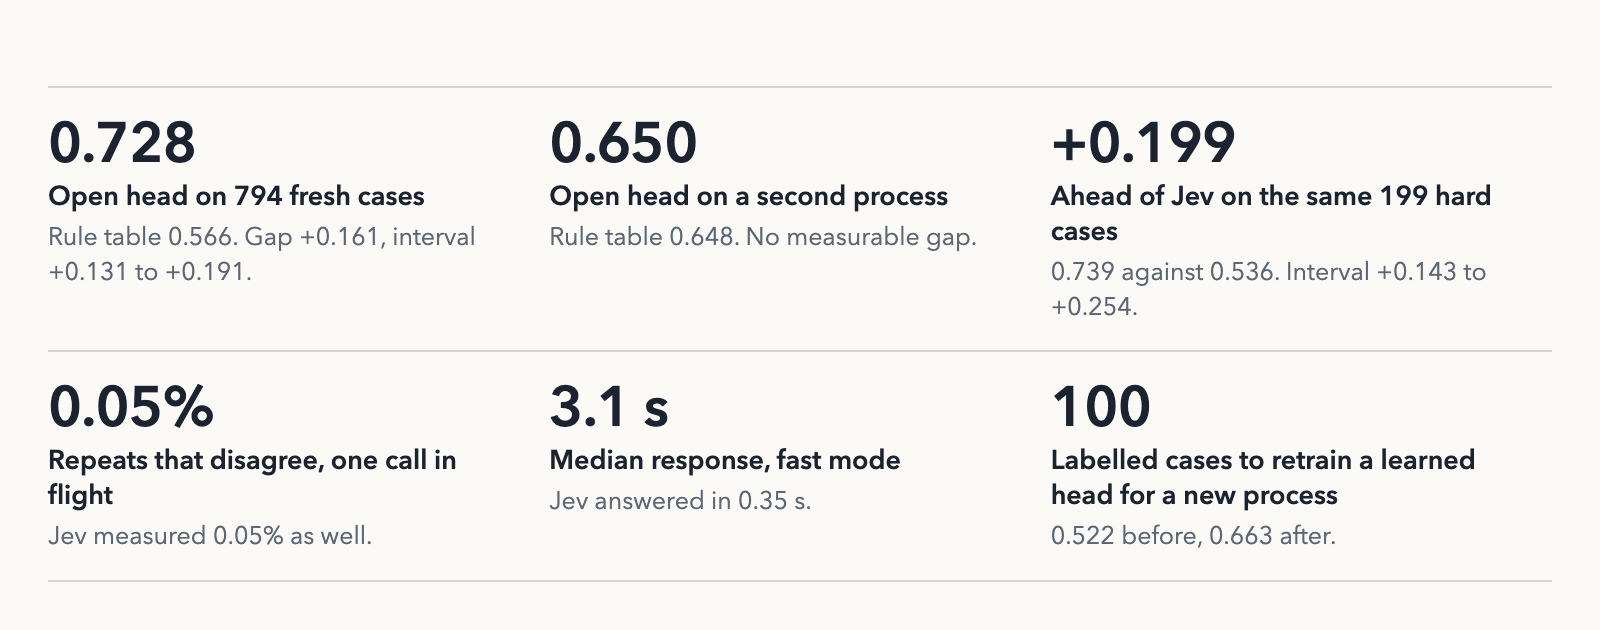
Watch the filmA retrained open decision head scored 0.728 against 0.566 for a rule table on 800 fresh cases, a gap that excludes zero; the first round missed, with 0.545 against 0.575 (gap -0.029, interval +0.001 to -0.060).
Read the campaignReading where a commitment ledger fails to balance found 0.80 of skipped steps at 745 tokens of reading; log review never reached 0.80 at any budget.
Read the campaignWith the monitoring budget held flat, sprawl cost grows as fleet size to the power 1.4665 (95% interval 1.4101 to 1.5230); with per-agent monitoring it is 0.9001.
Read the campaignCoupling a fleet adds at most 0.013 to error correlation, against +0.447 from shared weights; the rise in errors came from longer prompts.
Read the campaignOf six charter clauses, only boundaries, decision rules and escalation conditions changed agent behaviour; mandate, reporting and revocation had no measurable effect.
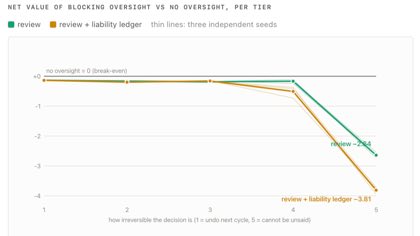
Read the campaignThe registered prediction that review pays on irreversible decisions failed in all 12 series; a liability ledger raised wrongful blocking at the top tier to 42.7%.
Read the campaignTwo pre-registered studies stopped on rules written before they ran. One of them also retracts a published claim.
Read the campaignEach added level of delegation depth costs 1.50 on the quality margin; reviewer capacity buys back the most at +1.46.
Read the campaignThe same model on different silicon shares its errors (phi +0.447 on contested items); models from different families do not (mean phi −0.102).
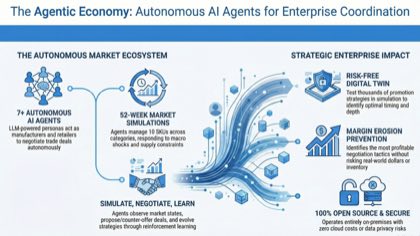
Read the campaign100 runs across 4 industry verticals, 5 enterprises of 150 agents each per run: a first-mover premium of 210%, with the market tipping in 77% of markets.
Read the campaignLab notebook
18 published studies, most of them pre-registered simulations: agent oversight, delegation, supply-chain stress and multi-agent markets.
Latest study ·
A pre-registered simulation held hourly monitoring of an agent fleet and six-hourly inspection to the same nominal reviewer budget, and found the budget at which hourly monitoring starts to catch faults.
Read on Medium Read on LinkedInA preregistered study of how often a model judge agrees with itself on 197 blind case files, and how far down one model family a judge stays usable.
Oversight & accountability
A retrained open decision head beat both a rule table and the hosted service on 800 fresh cases, after a first version that did not.
The agentic enterprise
Agent logs record what happened and have no row for what didn’t. A pre-registered test of commitment accounting, an obligation ledger reconciled against executed calls, for catching omissions in procurement-workflow traces.
Oversight & accountability
AGENESIS-2 adds a portfolio layer to the AGENESIS enterprise simulation to measure whether agent sprawl costs more than proportionally under a fixed monitoring budget.
Oversight & accountability
The executive reading of the sprawl-cost result.
Oversight & accountability
A pre-registered test of whether making an AI supervisor answerable for past harm improves its oversight, and why it backfired across irreversibility tiers.
Oversight & accountability
A controlled experiment on the cost of wrongful blocks and the incentives that shape an AI reviewer.
Oversight & accountability
A simulation sweeping twelve dimensions of organisational design to price the bet that moving work further from human review is cheaper. Delegation depth carries the strongest weight, and it is negative.
Oversight & accountability
One model on two machines, with different quantisation and serving stacks, made the same mistakes. What separates one reviewer from another is the model family: a case for dissimilar redundancy.
Oversight & accountability
Difficulty is a property of the work; risk is a property of the consequences. Testing, in simulation and as a product, the rule that decides which agentic decisions a person must see.
Oversight & accountability
45,312 simulated supply-network designs, each run through a year of compounding disruption, and the exact stress level at which service breaks.
The agentic enterprise
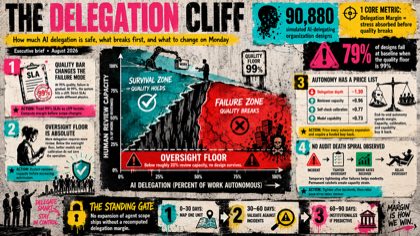
90,880 simulated designs of an AI-delegating organization. At a 95% quality floor they degrade gradually; at 99% the same design space develops a cliff.
Oversight & accountability
An inventory-planning experiment explores which kinds of stress prepare a policy for unfamiliar disruptions.
The agentic enterprise
Results from a 100-run multi-agent enterprise simulation across four…
The agentic enterprise
What a Controlled Experiment Reveals About Enterprise AI…
The agentic enterprise
Manufacturer and retailer agents negotiate promotions inside a simulated market with competing incentives.
The agentic enterprise
The machinery behind the studies
Several experiments run on AGENESIS and the other systems profiled in the workshop.
Unpublished
Working pieces and explorations that live only on this site.
What a simulation suggests about the cost of overseeing a growing agent portfolio.
Read moreA controlled simulation of how a record of past harm affected an AI supervisor.
Read moreA pre-registered simulation held hourly monitoring of an agent fleet and six-hourly inspection to the same nominal reviewer budget, and found the budget at which hourly monitoring starts to catch faults.
Read moreHow often a model judge agrees with itself on 197 blind case files, and how far down one model family a judge stays usable.
Read more“Better questions lead to better worlds.”Dinand Tinholt